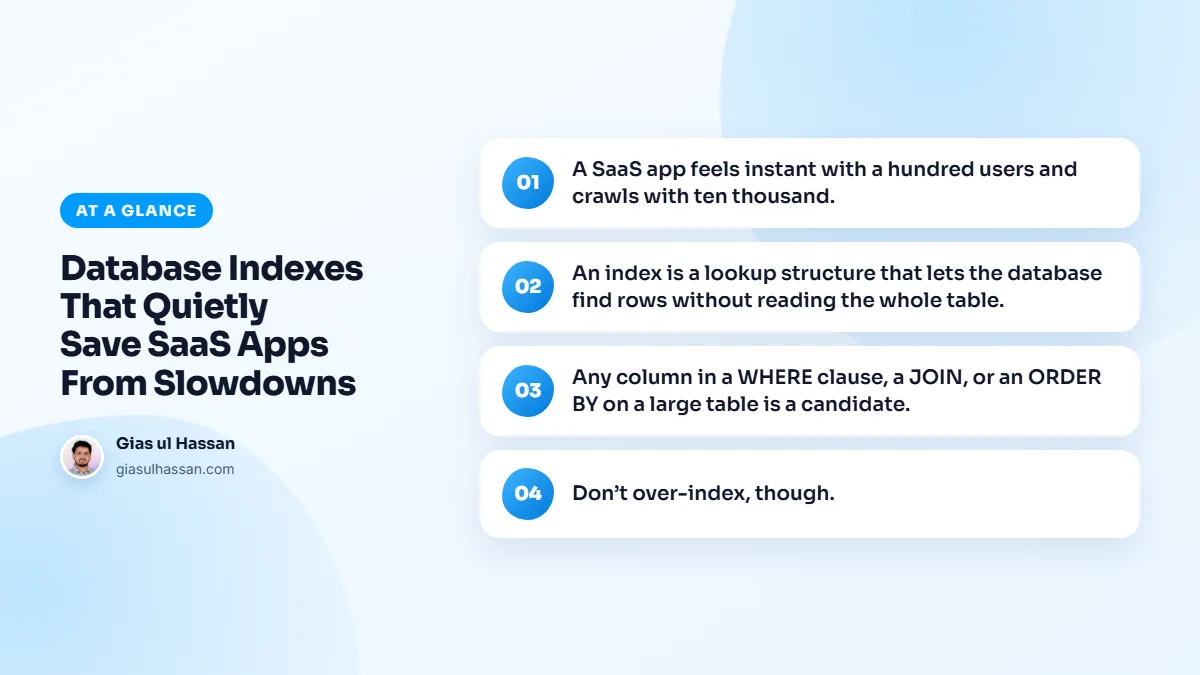
A SaaS app feels instant with a hundred users and crawls with ten thousand. Nothing in the code changed: the data grew, and queries that scanned a small table now scan a huge one. The fix is almost always database indexes, and the gains are dramatic for how little work they take.
What an index actually does
An index is a lookup structure that lets the database find rows without reading the whole table. Without one, finding a user by email in a million-row table means checking up to a million rows. With one, it’s a handful. The slowdown is invisible until the table is big, which is exactly why it surprises growing apps.
The default index in most relational databases is a B-tree: a sorted structure the database can walk down in a few steps instead of reading every row. Because it is sorted, the same index also helps with range filters like "created this month" and with sorting. The PostgreSQL chapter on indexes is a readable introduction, even if you run something else.
Index what you filter and join on
Any column in a WHERE clause, a JOIN, or an ORDER BY on a large table is a candidate. The classic wins are foreign keys (the user_id you join on constantly) and lookup fields like email or slug. Use your database’s EXPLAIN on slow queries. It tells you whether a query uses an index or scans the table. A full table scan on a large table is the signal to add one.
Which database indexes to add first
In the SaaS apps I work on, the same few patterns cover most slow queries:
- Foreign keys. Every
user_id,account_idorproject_idyou join on. MySQL’s InnoDB creates an index for a foreign key if one doesn’t already exist. PostgreSQL does not, so on Postgres you add them yourself. - Tenant columns. In a multi-tenant app nearly every query filters by account first. That column belongs at the front of most composite indexes.
- Lookup fields. Email, slug, API key, invite token: anything you fetch a single row by. Make them unique indexes where the data should be unique, and you get a correctness guarantee for free.
- Status and date filters on big tables. "Open invoices for this account, newest first" is a classic query that wants a composite index.
Composite indexes and column order
An index on several columns is used from left to right. An index on (account_id, created_at) serves "this account’s rows, newest first" well, and also serves queries on account_id alone. It does not help a query that only filters on created_at. Put the columns you match exactly first, then the one you range over or sort by. MySQL explains this leftmost prefix rule in its guide to multiple-column indexes.
How to find the slow queries
Guessing wastes time. Let the database tell you where it hurts:
- Turn on slow query logging. MySQL has a slow query log. PostgreSQL can log any statement over a threshold with
log_min_duration_statement, and thepg_stat_statementsextension totals the time spent per query. - Sort by total time, not just the slowest single run. A modest query that runs on every page load matters more than a slow monthly report.
- Run
EXPLAINon the worst offenders (EXPLAIN ANALYZEin PostgreSQL actually runs the query and shows real timings). Look for full or sequential scans on large tables. - Add one index, run
EXPLAINagain, and confirm the plan changed before moving on.
Test against production-sized data. On a development database with fifty rows, the planner will happily scan the table because that is faster than using an index, and every query looks fine.
Adding indexes without downtime
Building an index on a large, busy table can block writes while it runs. PostgreSQL offers CREATE INDEX CONCURRENTLY to avoid that, at the cost of a slower build. Modern MySQL builds most InnoDB secondary indexes online. Either way, add big indexes during quiet hours and watch the server while they build.
When indexes hurt
Don’t over-index, though. Every index makes writes slightly slower and uses space, so indexing every column is its own problem. Index what you actually query often.
A few signs you have gone too far: indexes that duplicate each other (one on account_id is redundant next to one on (account_id, created_at)), indexes the statistics show are never used, and write-heavy tables like event logs carrying a pile of indexes. In PostgreSQL the pg_stat_user_indexes view shows how often each index is scanned, which makes unused ones easy to spot.
Indexes also can’t save every query. A filter wrapped in a function, such as LOWER(email), won’t use a plain index on email; you need an expression index, or store the value already lowercased. A LIKE search with a leading wildcard can’t use a normal B-tree index at all. And loading thousands of rows the user never sees is a pagination problem, not an index problem.
Fix the query before buying a bigger server
Most "we need a bigger server" fires are really three missing indexes. A larger machine hides a full table scan for a while. Then the data doubles again and you are back where you started, paying more each month. An index fixes the cause.
Speed is one half of keeping an app healthy as it grows. The other half is protecting it from traffic it shouldn’t serve, which is where rate limiting a SaaS API without punishing real users comes in. The same measure-first habit applies to your marketing site: speed is one of the checks in why a website is not ranking on Google, and on WordPress the database is often part of the story in how to speed up a WordPress site.
If your app is getting slower as it grows and you want someone to find the queries responsible, that is routine work in my SaaS development service.